State-of-the-art AI model research, put into production
An experiment is only finished when it runs in a product.
I plan, run and publish model research — the essay-scoring model that reached state of the art in its paper went straight into a million-user product. The habit of measuring before shipping comes from the same place.
The published work
Rubric-Specific Approach to Automated Essay Scoring with Augmentation Training (arXiv:2309.02740). Planned, designed, executed and authored by me, from research question to published paper: a state-of-the-art result on automated essay scoring. The model it describes went into production and scored essays for nearly a million learners.
Other research
- Optimised prompt selection using a task-specific model and LLM feedback (conference submission).
- Reward modelling and reinforcement learning from human feedback (T5 reward model + PPO).
- Hallucination detection for LLM answers (2025) — shipped as the fact-checking SDK.
- Earlier applied work: SKU-level and agri-food sales prediction, spatial clustering of migratory birds for avian-flu surveillance, smart-livestock and soil-sensor modelling, and risk signals from PC log data.
More work
All case studies
Consulting AI inside a farming enterprise's app
The company's agronomy know-how — guidelines, past reports, consultants' calls — answers farmers' questions with citations and drafts the consultants' reports for them.
Live in production · pilot expanding to all farms from May 2026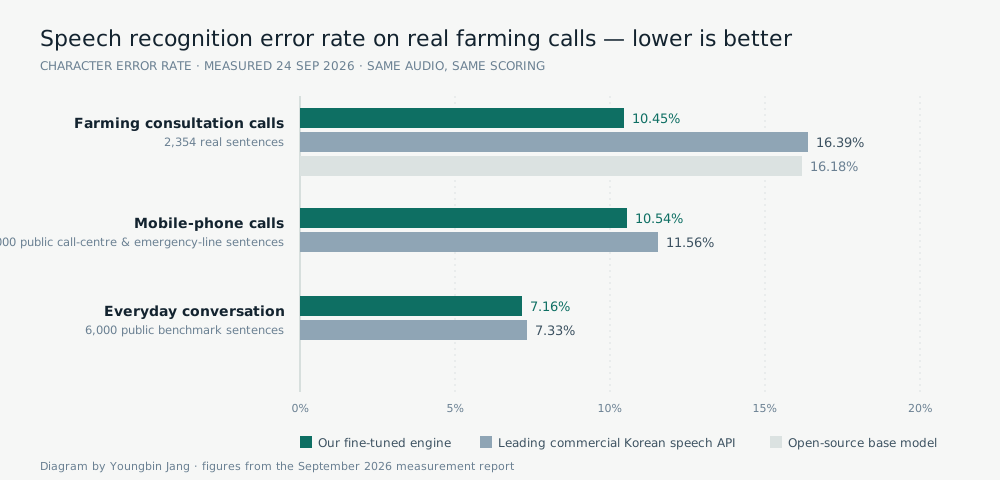
Speech recognition that beats the commercial API on real farm calls
Consultants' phone calls become farming diaries and consulting reports. On real farming calls our fine-tuned engine makes 10.45% character errors; the leading commercial Korean speech API makes 16.39%.
10.45% error on real farming calls vs 16.39% for the leading commercial API