Speech recognition that beats the commercial API on real farm calls
Trained on 1% of the client's own calls. The other 99% is the roadmap.
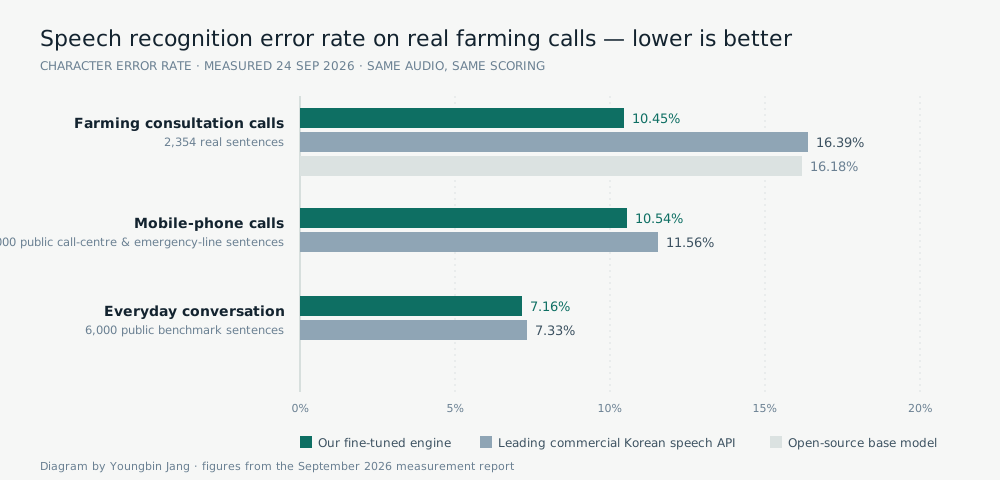
Consultants' phone calls become farming diaries and consulting reports. On real farming calls our fine-tuned engine makes 10.45% character errors; the leading commercial Korean speech API makes 16.39%.
What they needed
Consultants speak with farmers by phone all day. Those calls hold the facts that should end up in the farm’s diary and the consultation report. But generic speech recognition mangled the crop names, chemicals, brand names and local terms, and users stopped trusting the transcripts. Off-the-shelf engines are trained to score well on news and studio conversation; nobody optimises them for farming calls on a mobile phone.
What I built
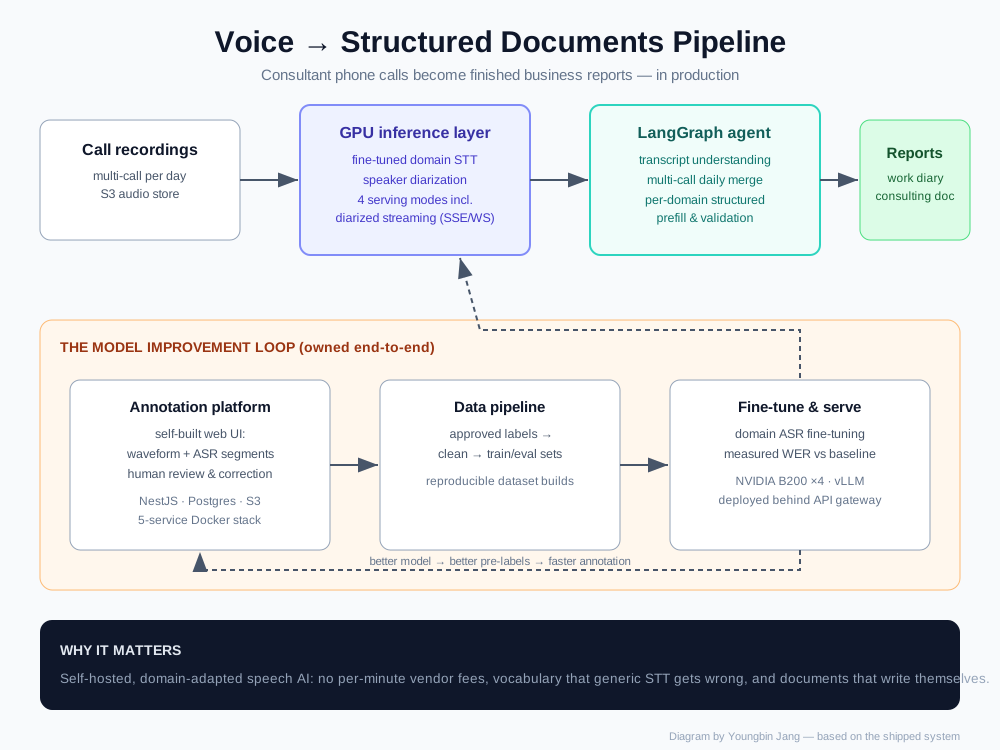
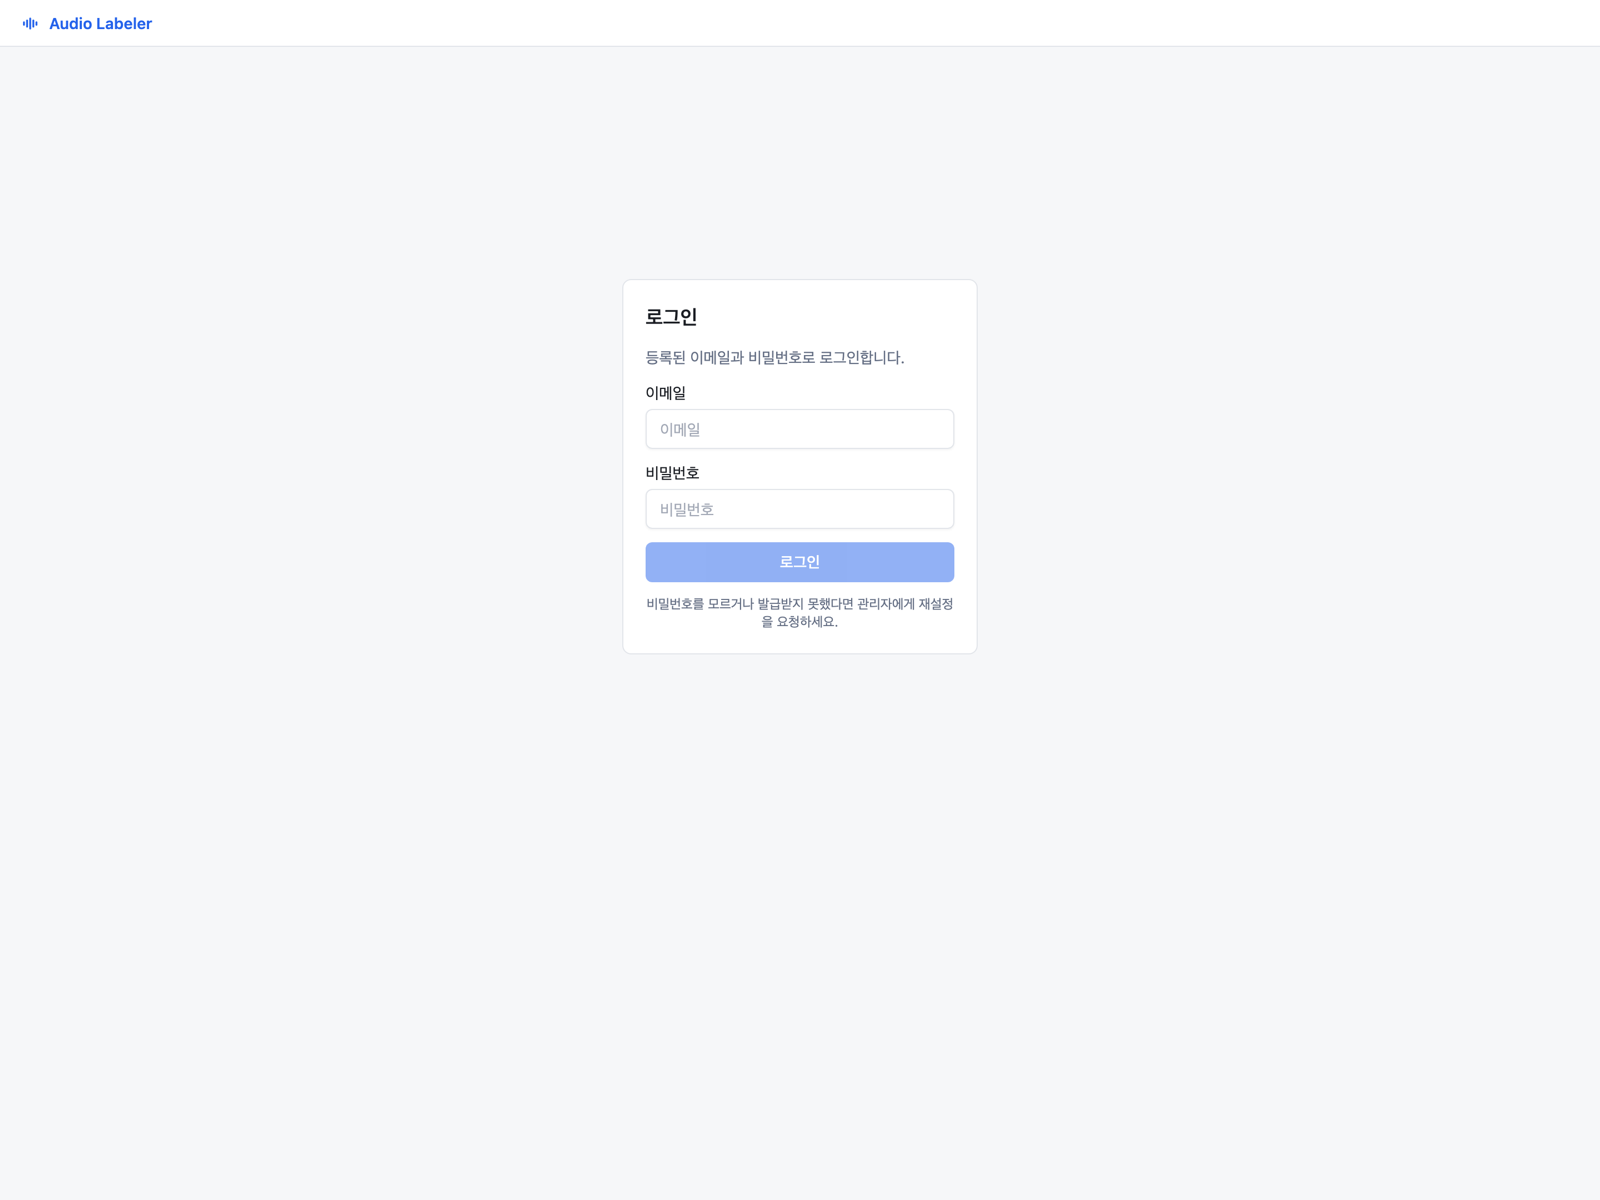
Four parts. A human-review platform where the team corrects transcripts and builds the training set. A fine-tuned speech model with speaker separation, served on the company’s own GPUs. A 56,000-entry farming vocabulary that feeds recognised terms back to the engine as hints. And a gateway that every other system calls — batch or streaming, with or without speaker labels. Downstream, the transcript feeds the report copilot.
What changed
Measured on 2,354 sentences from the client’s real calls, with the same scoring rules for every engine. Our engine: 10.45% character error rate. The leading commercial Korean speech API: 16.39%. The open-source model we started from: 16.18%. On everyday conversation the engine stays level with the commercial API (7.16% vs 7.33%), and on public mobile-phone recordings it is ahead (10.54% vs 11.56%). By the industry’s usual reading, around 20% is “usable but double-check” and around 10% is “trusted”. The client moved from the first band to the second — with only about 1% of their recorded calls labelled.
More work
All case studies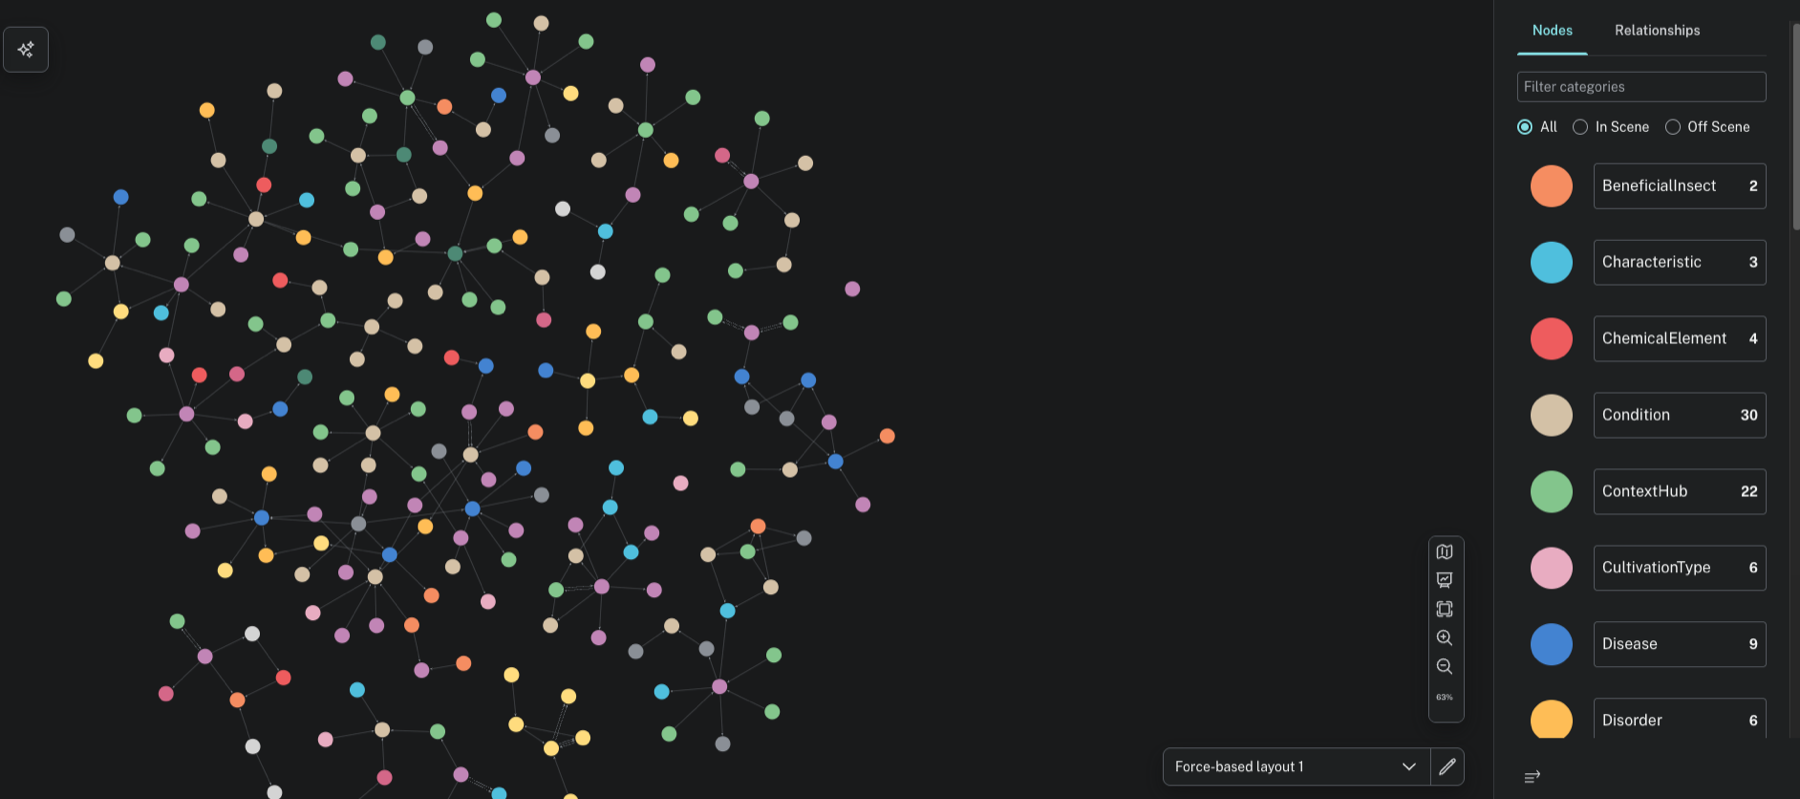
Consulting AI inside a farming enterprise's app
The company's agronomy know-how — guidelines, past reports, consultants' calls — answers farmers' questions with citations and drafts the consultants' reports for them.
Live in production · pilot expanding to all farms from May 2026
Scoring a million learners' essays and speech
An English-test practice service needed instant, reliable scores for essays and spoken answers — at a scale no human grading or per-call vendor bill could support.
Nearly 1M users · supported a $5M+ raise