Catching an AI's made-up claims before the user does
Five stars, eighteen thousand dollars, and a component you can drop into any pipeline.
An AI answer is split into individual claims; each claim is checked against the reference documents, and the answer is rewritten around exactly the claims that failed.
What they needed
Their product answered questions from reference documents, and sometimes the answers contained things the documents never said. They needed to know which sentence was wrong, automatically, and to fix the answer rather than throw it away.
What I built
A pipeline that turns an answer into subject–predicate–object claims and checks each claim against the reference. When too many fail, it re-prompts with the exact failure map, so the rewrite fixes what was wrong and keeps what was right. Delivered as an installable SDK with baselines and an evaluation kit so the client can measure it on their own data.
What changed
The client left a five-star review. The component is transferable: it plugs into any question-answering system that has reference text.
More work
All case studies
Consulting AI inside a farming enterprise's app
The company's agronomy know-how — guidelines, past reports, consultants' calls — answers farmers' questions with citations and drafts the consultants' reports for them.
Live in production · pilot expanding to all farms from May 2026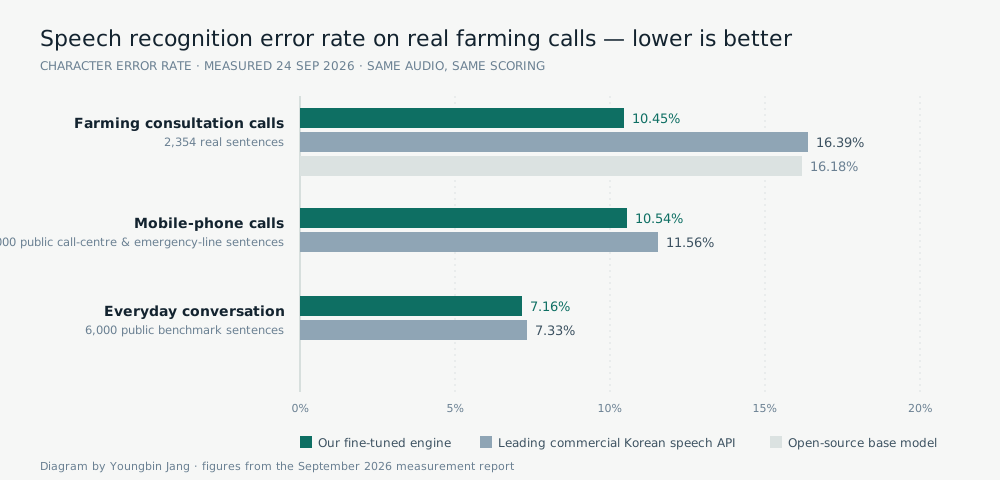
Speech recognition that beats the commercial API on real farm calls
Consultants' phone calls become farming diaries and consulting reports. On real farming calls our fine-tuned engine makes 10.45% character errors; the leading commercial Korean speech API makes 16.39%.
10.45% error on real farming calls vs 16.39% for the leading commercial API